
4 min read
Adversarial Attacks on Linear Models
I’ve been reading about adversarial attacks and wanted to implement something very simple. The simplest adversarial attack: attacking a linear model by Pierre Ablin helped me do just that and this blog post adapts a lot of material from there—check it out!
Setup
Suppose we have a binary classifier that has been trained on input-output pairs , with and . Our goal is to take base input and transform it to poison input such that
- its class would be guessed incorrectly by the classifier
- would remain similar to
If ’s represent images, then “similar” could mean that any introduced changes are visually imperceptible. For example, if we are dealing with two classes of digits, say 3’s and 7’s, from the MNIST database (), then our goal would be to take an image of a ‘7’ and make it look like a ‘3’ to the classifier but keep it looking like a ‘7’ to the human, and vice versa.
We will assume a classifier that makes predictions based on the sign of a linear regression model:
with and .
Thus, the decision boundary of the classifier is a hyperplane with equation
i.e. any point must satisfy the above equation.
Strategy
To have an input classified differently than , it must lie on the opposite side of the hyperplane1. To ensure visually imperceptible changes, a sensible strategy would be to move from as little as possible, i.e. perpendicularly towards the plane.
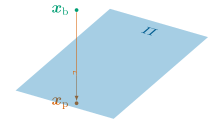
It might be useful to think of going from to in terms of the shortest distance from the hyperplane to . We can use vector to denote that:
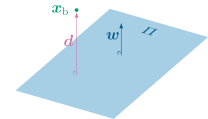
We can then express in the following way:
with .
This is useful because
- means is on the same side as , and the attack is unsuccessful
- means is on hyperplane
- means is on the opposite side to , and the attack is successful
However, we should express in terms of quantities we already know.
Notice that is perpendicular to the hyperplane and so is in the same (or opposite) direction as . We can thus say that (with ) and so
Further, we can find by considering the case of , when is on the hyperplane and thus must satisfy its equation:
Solving for gives
and so
Results
After achieving 95% test accuracy with the linear classifier, I attempted to evaluate the attack’s effectiveness. Such a simple strategy for manipulating the inputs yielded great results—I was definitely surprised. Here is how an image of a digit ‘7’ changes as we increase (remember, is already enough for misclassification, though the higher the , the more confident the classifier will be of its incorrect decision):
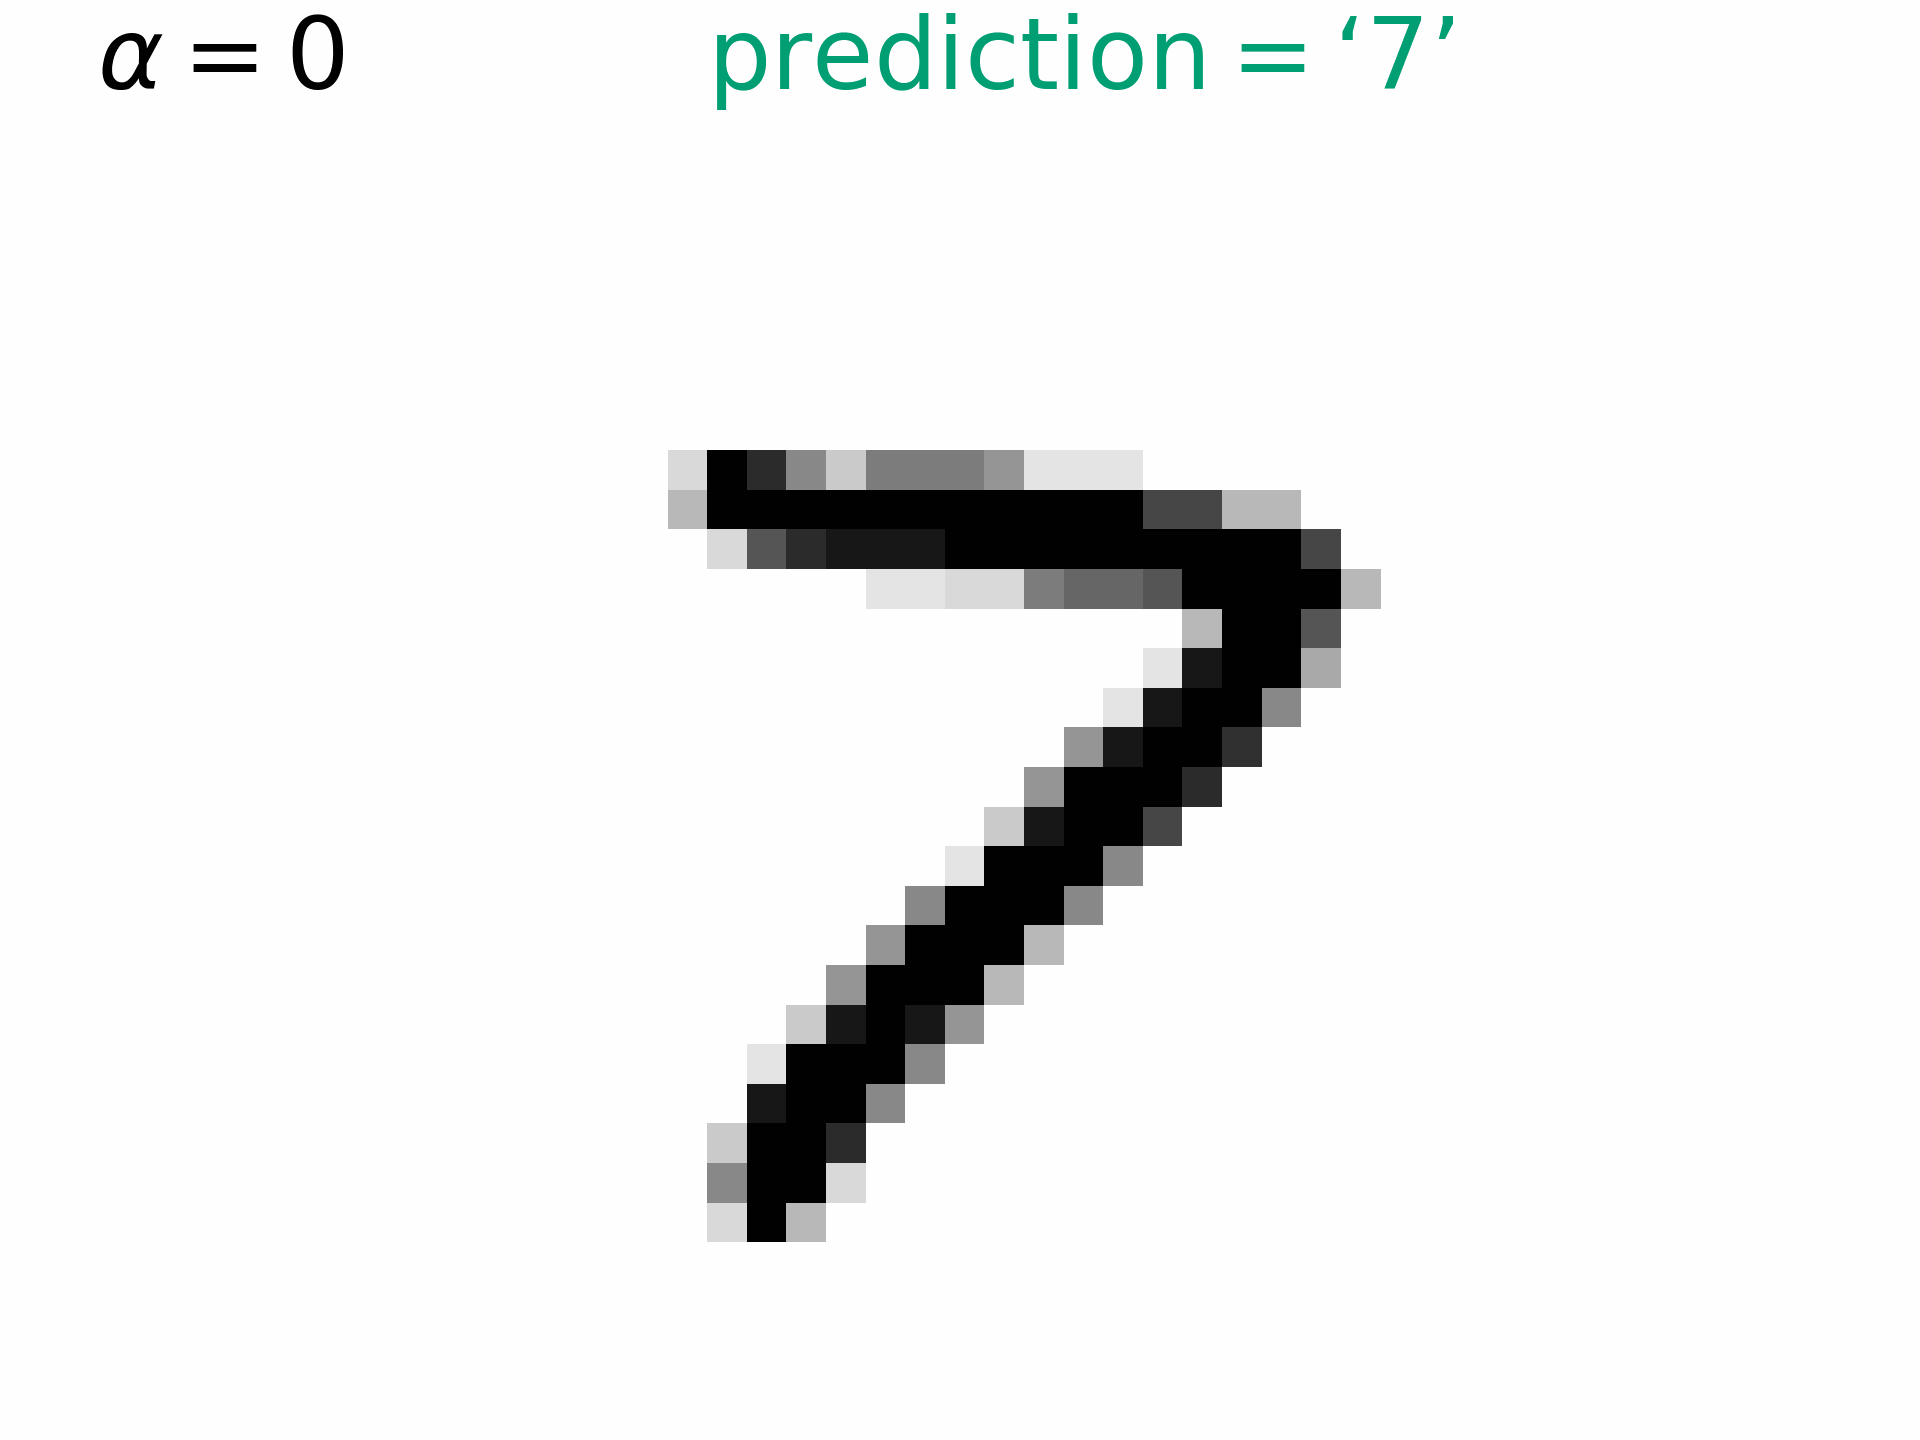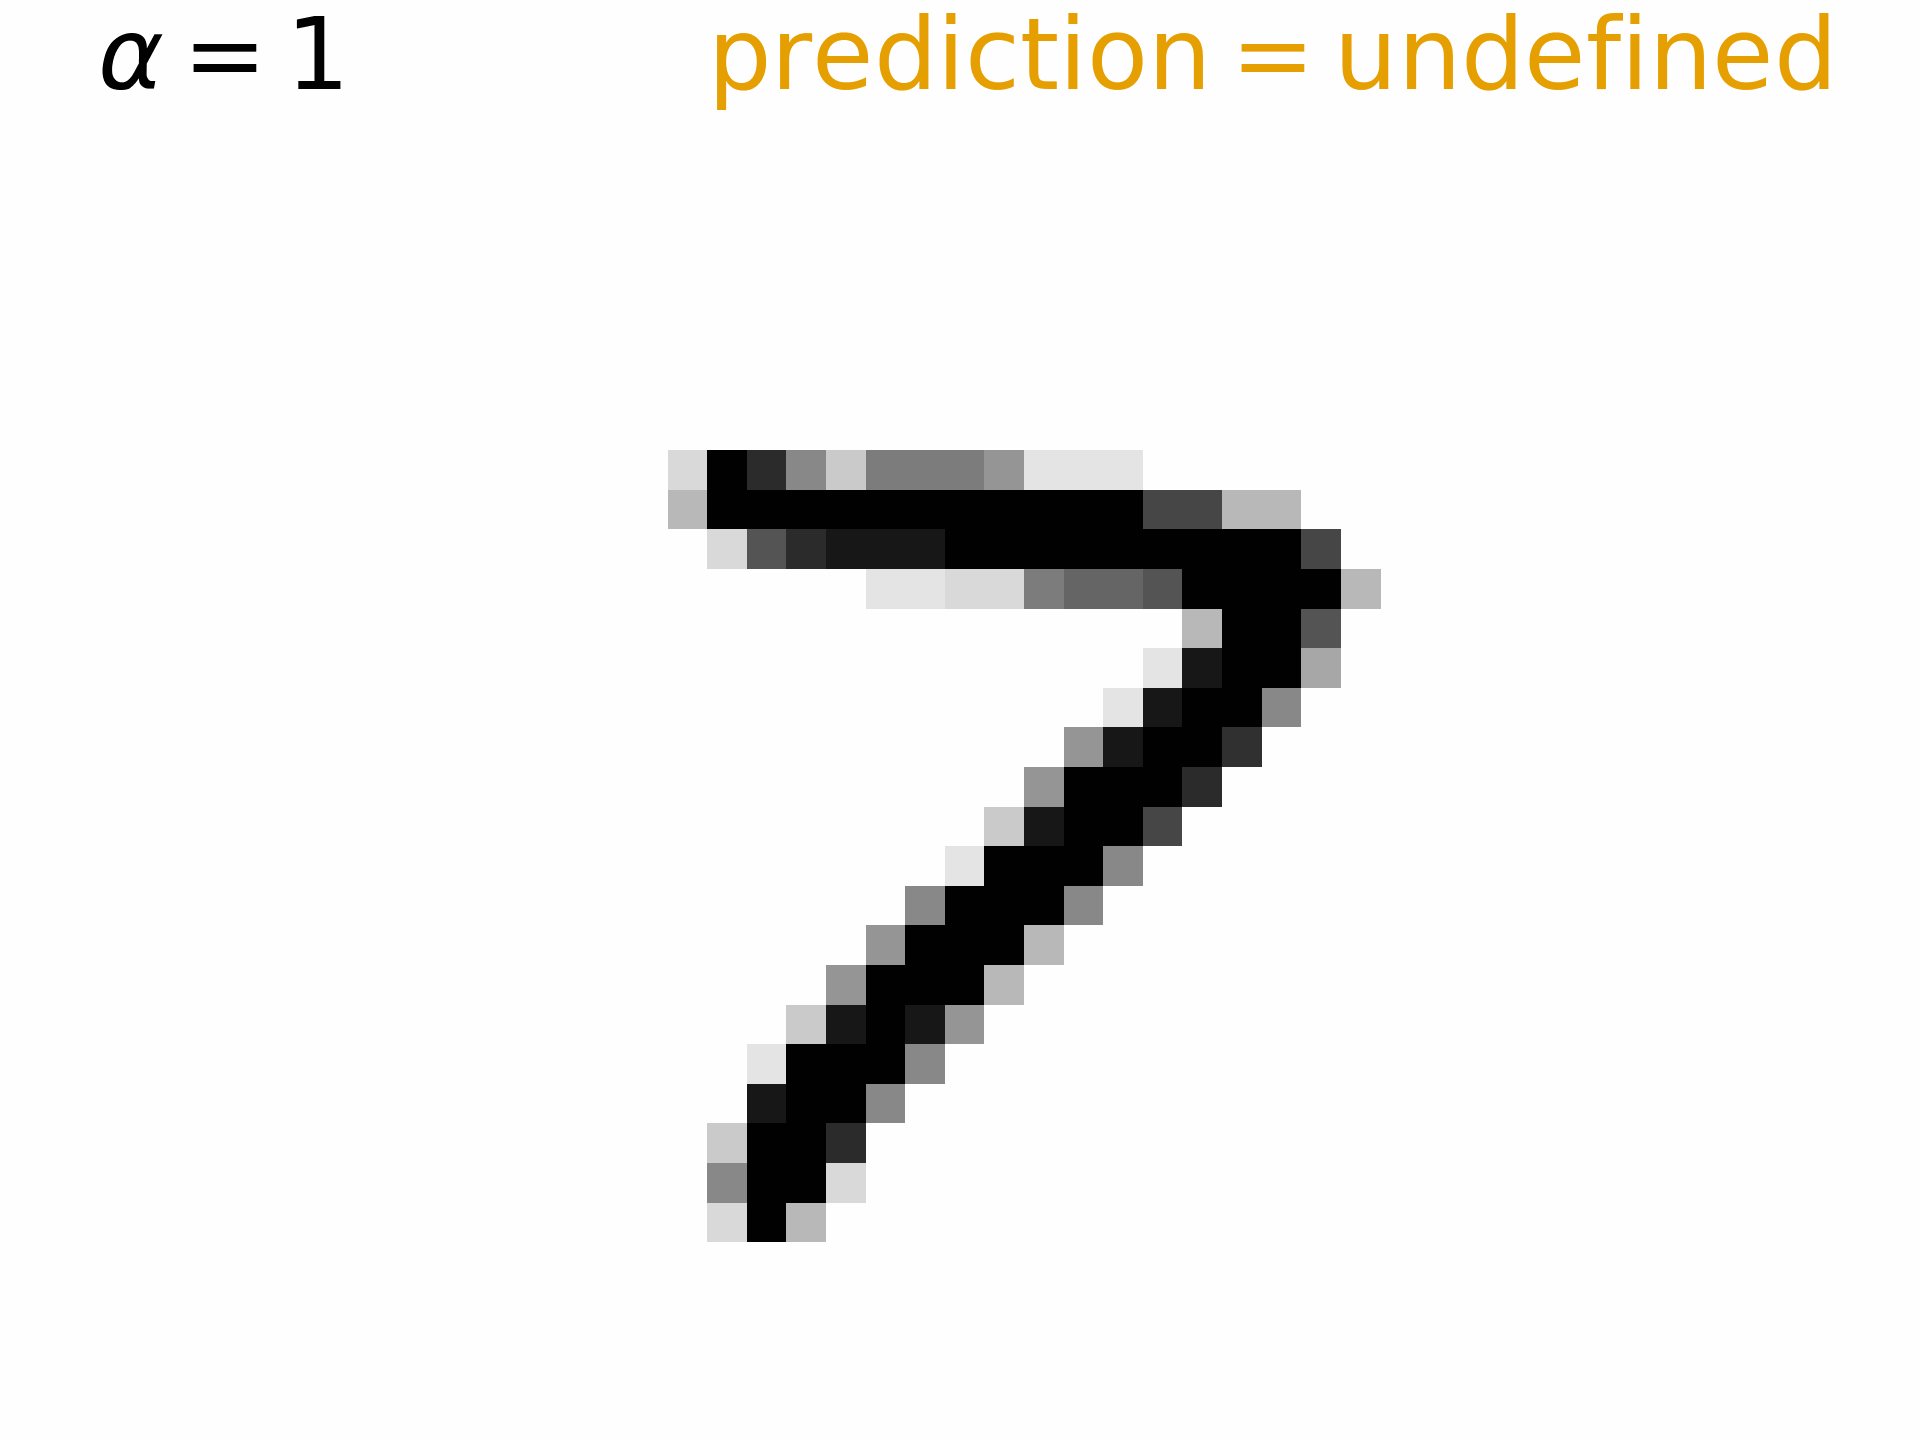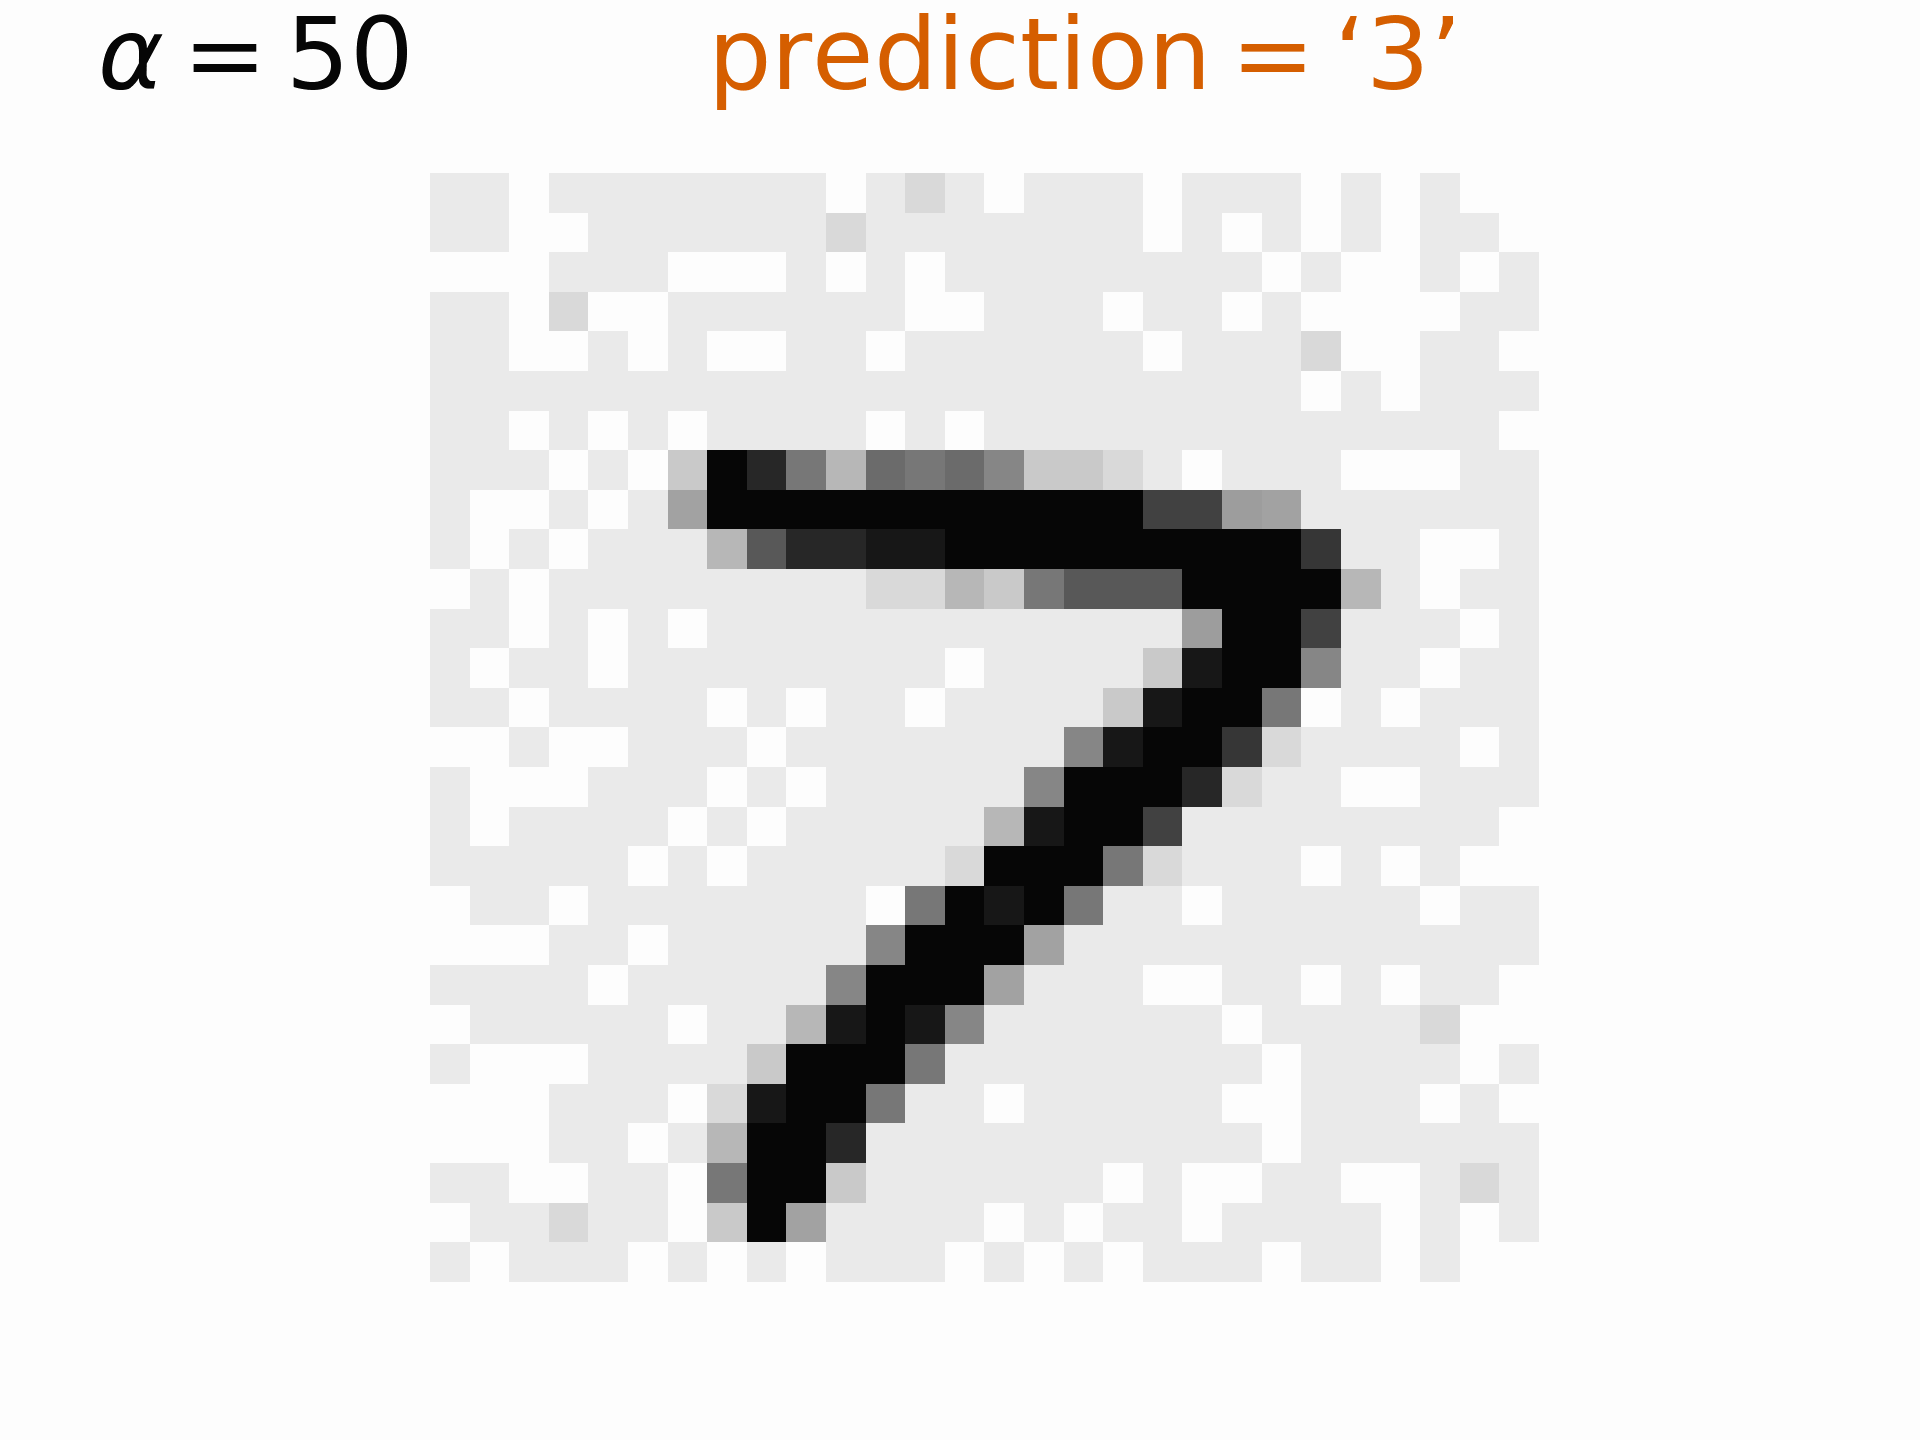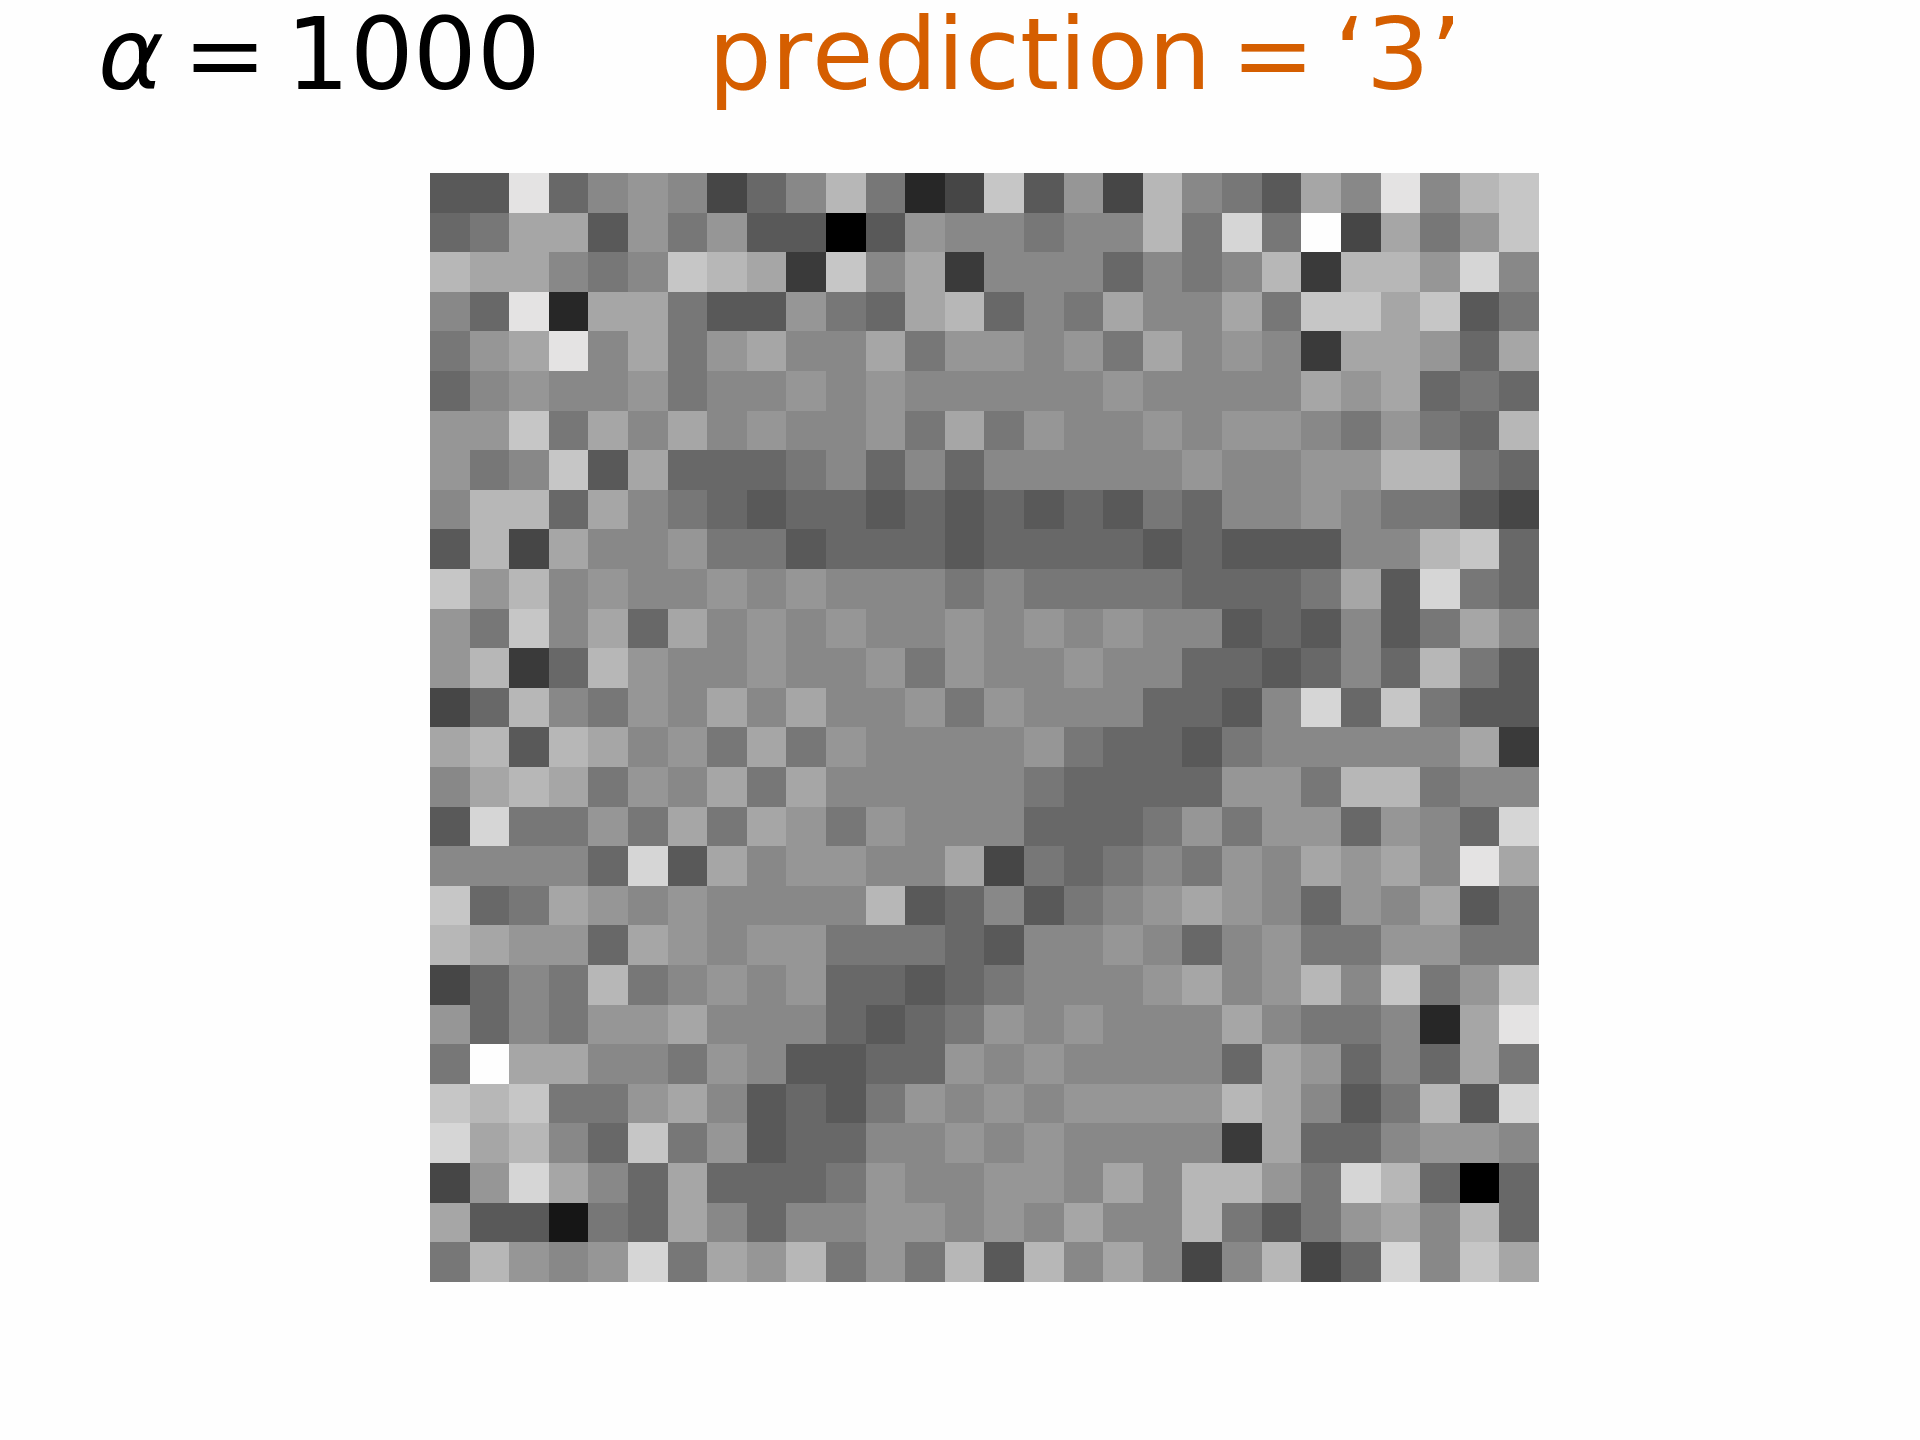
Personally, I didn’t notice any changes until (more than enough for misclassification!). But if I hadn’t observed the original image, I wouldn’t even know that something is wrong. Only at around do we see some funny stuff (mostly in the background pixels), where one may suspect that the images are being manipulated.
The strategy of moving perpendicularly towards the decision boundary made sense, but it wasn’t at all obvious to me that the resulting poisoned image wouldn’t look drastically different. Of course, this whole “attack” assumed a lot of knowledge and power to change things on the attacker’s side, but it is still interesting why something like this could potentially work so well. It could be that my genuine surprise comes from looking at the 2D representations of the hyperplane in the diagrams above and interpreting movement in any direction as incredibly consequential. Indeed, some existing works speculate that the effectiveness of adversarial attacks is partly due to high dimensionality of the models (even a linear classifier for MNIST has parameters), but, so far, I haven’t found truly satisfactory explanations. I’ll have to keep looking, but please let me know if you are aware of any relevant literature!
Bonus chicanery
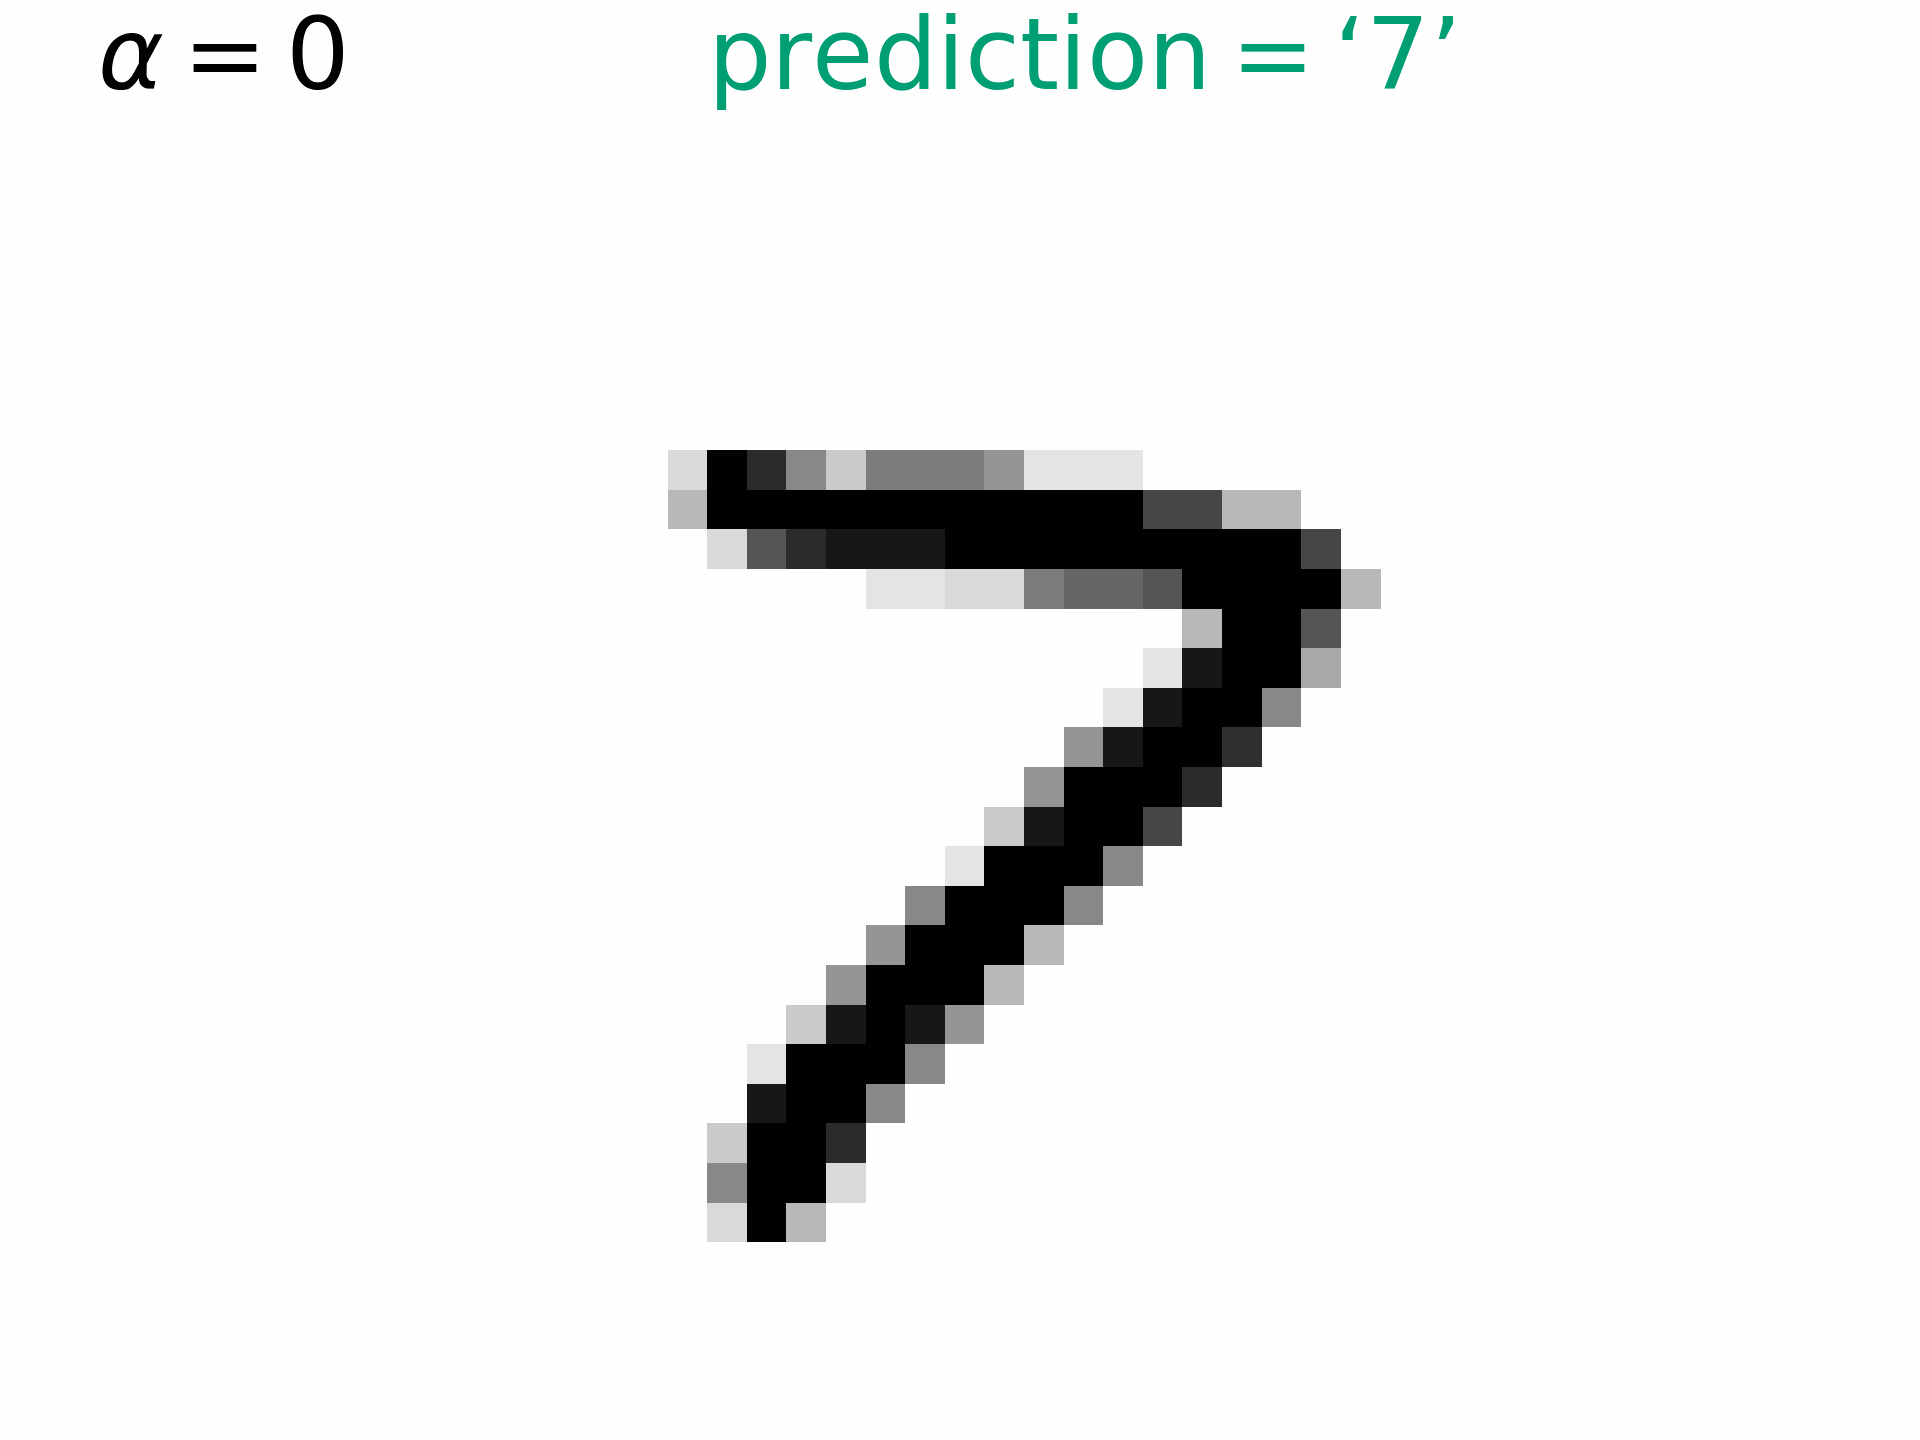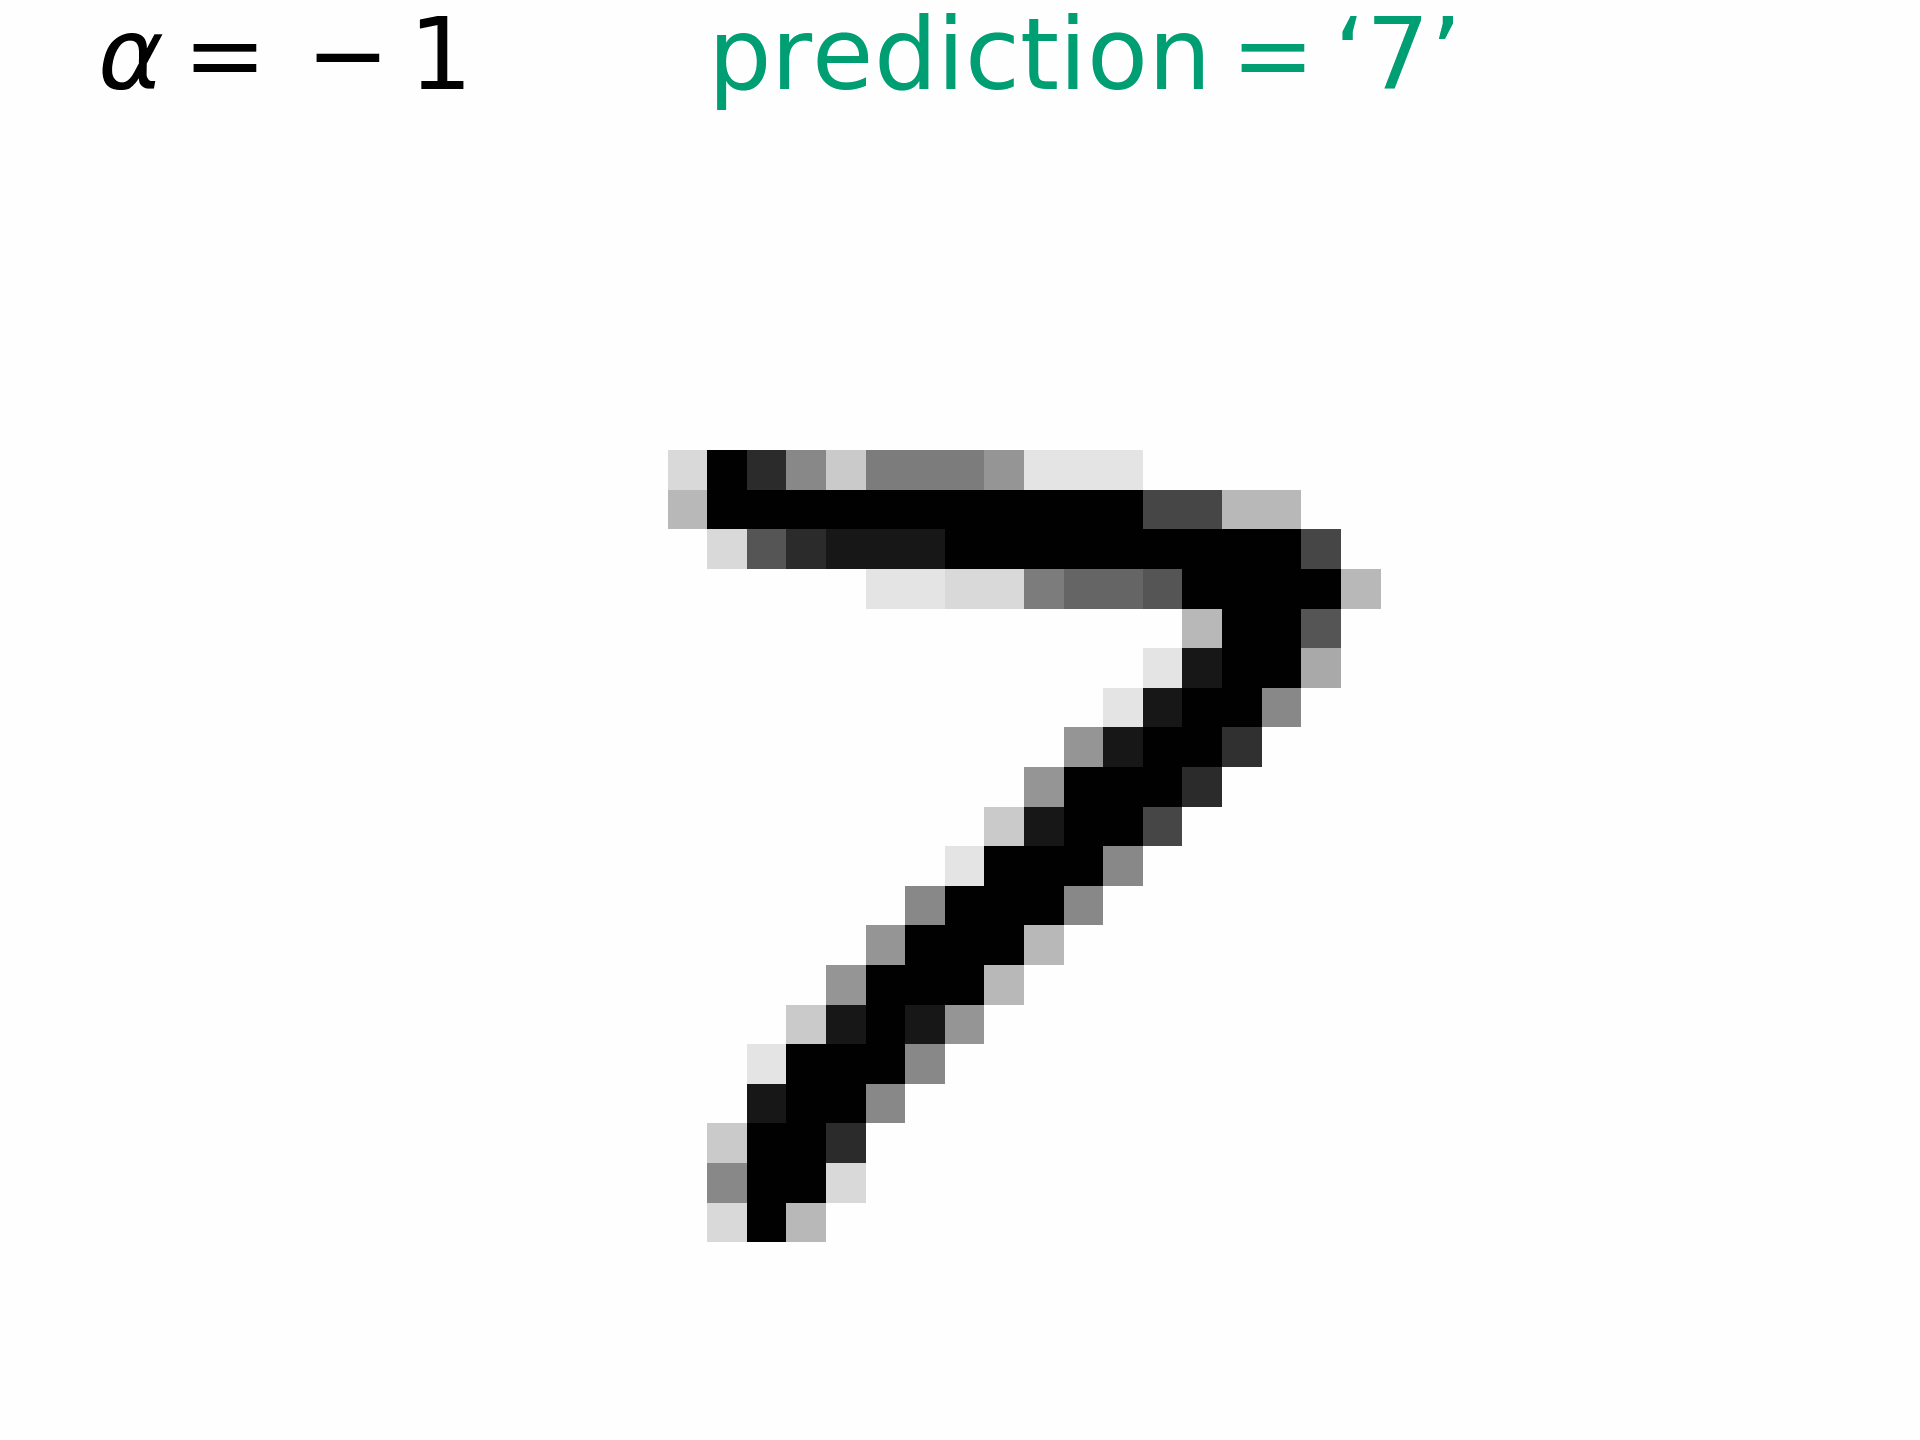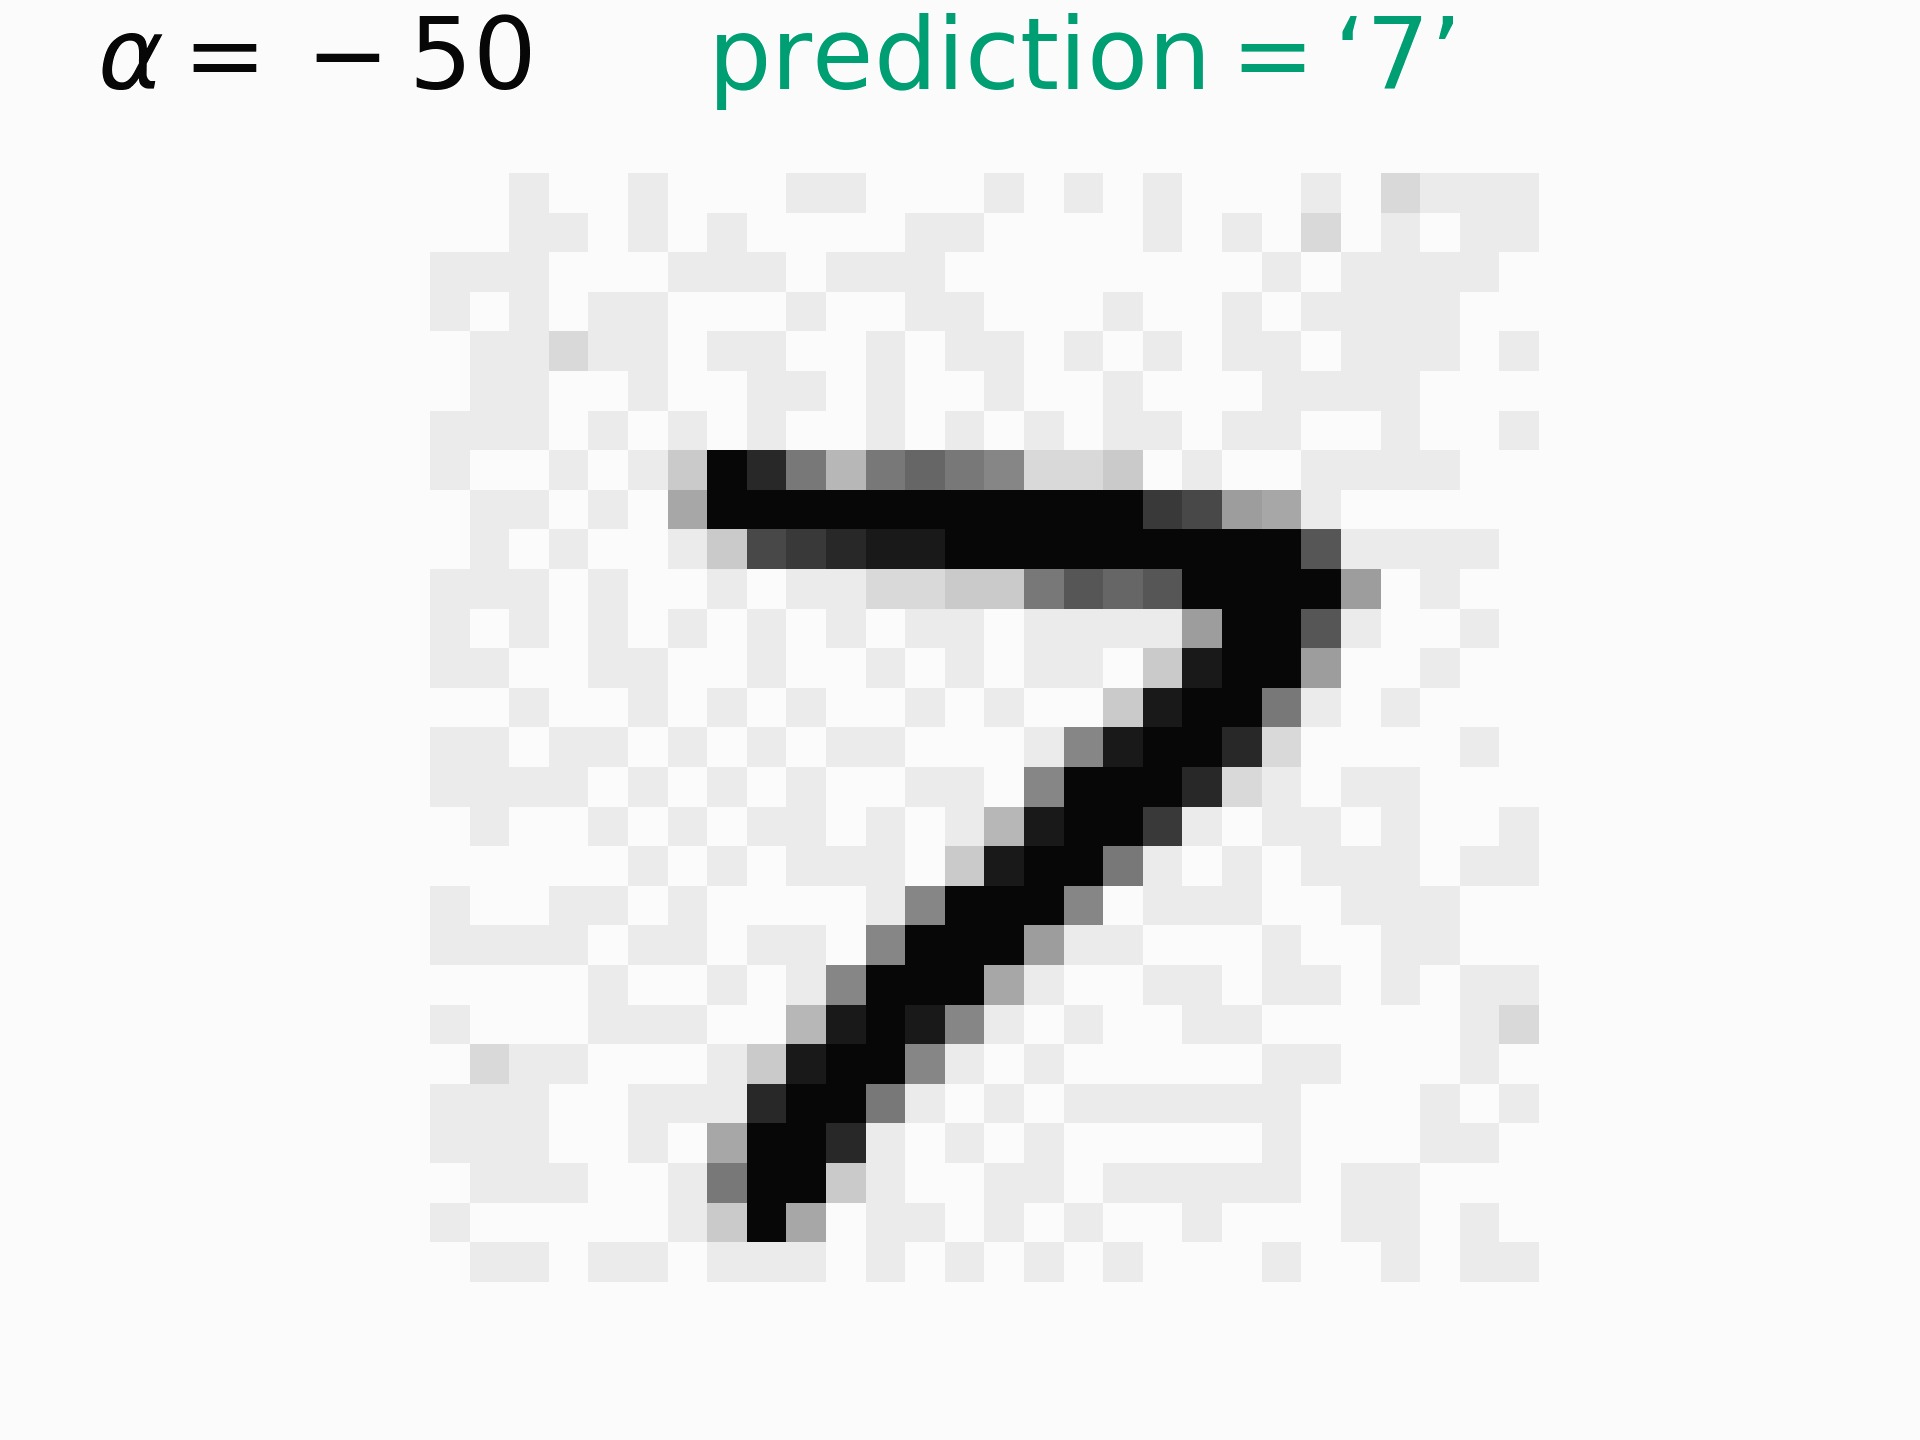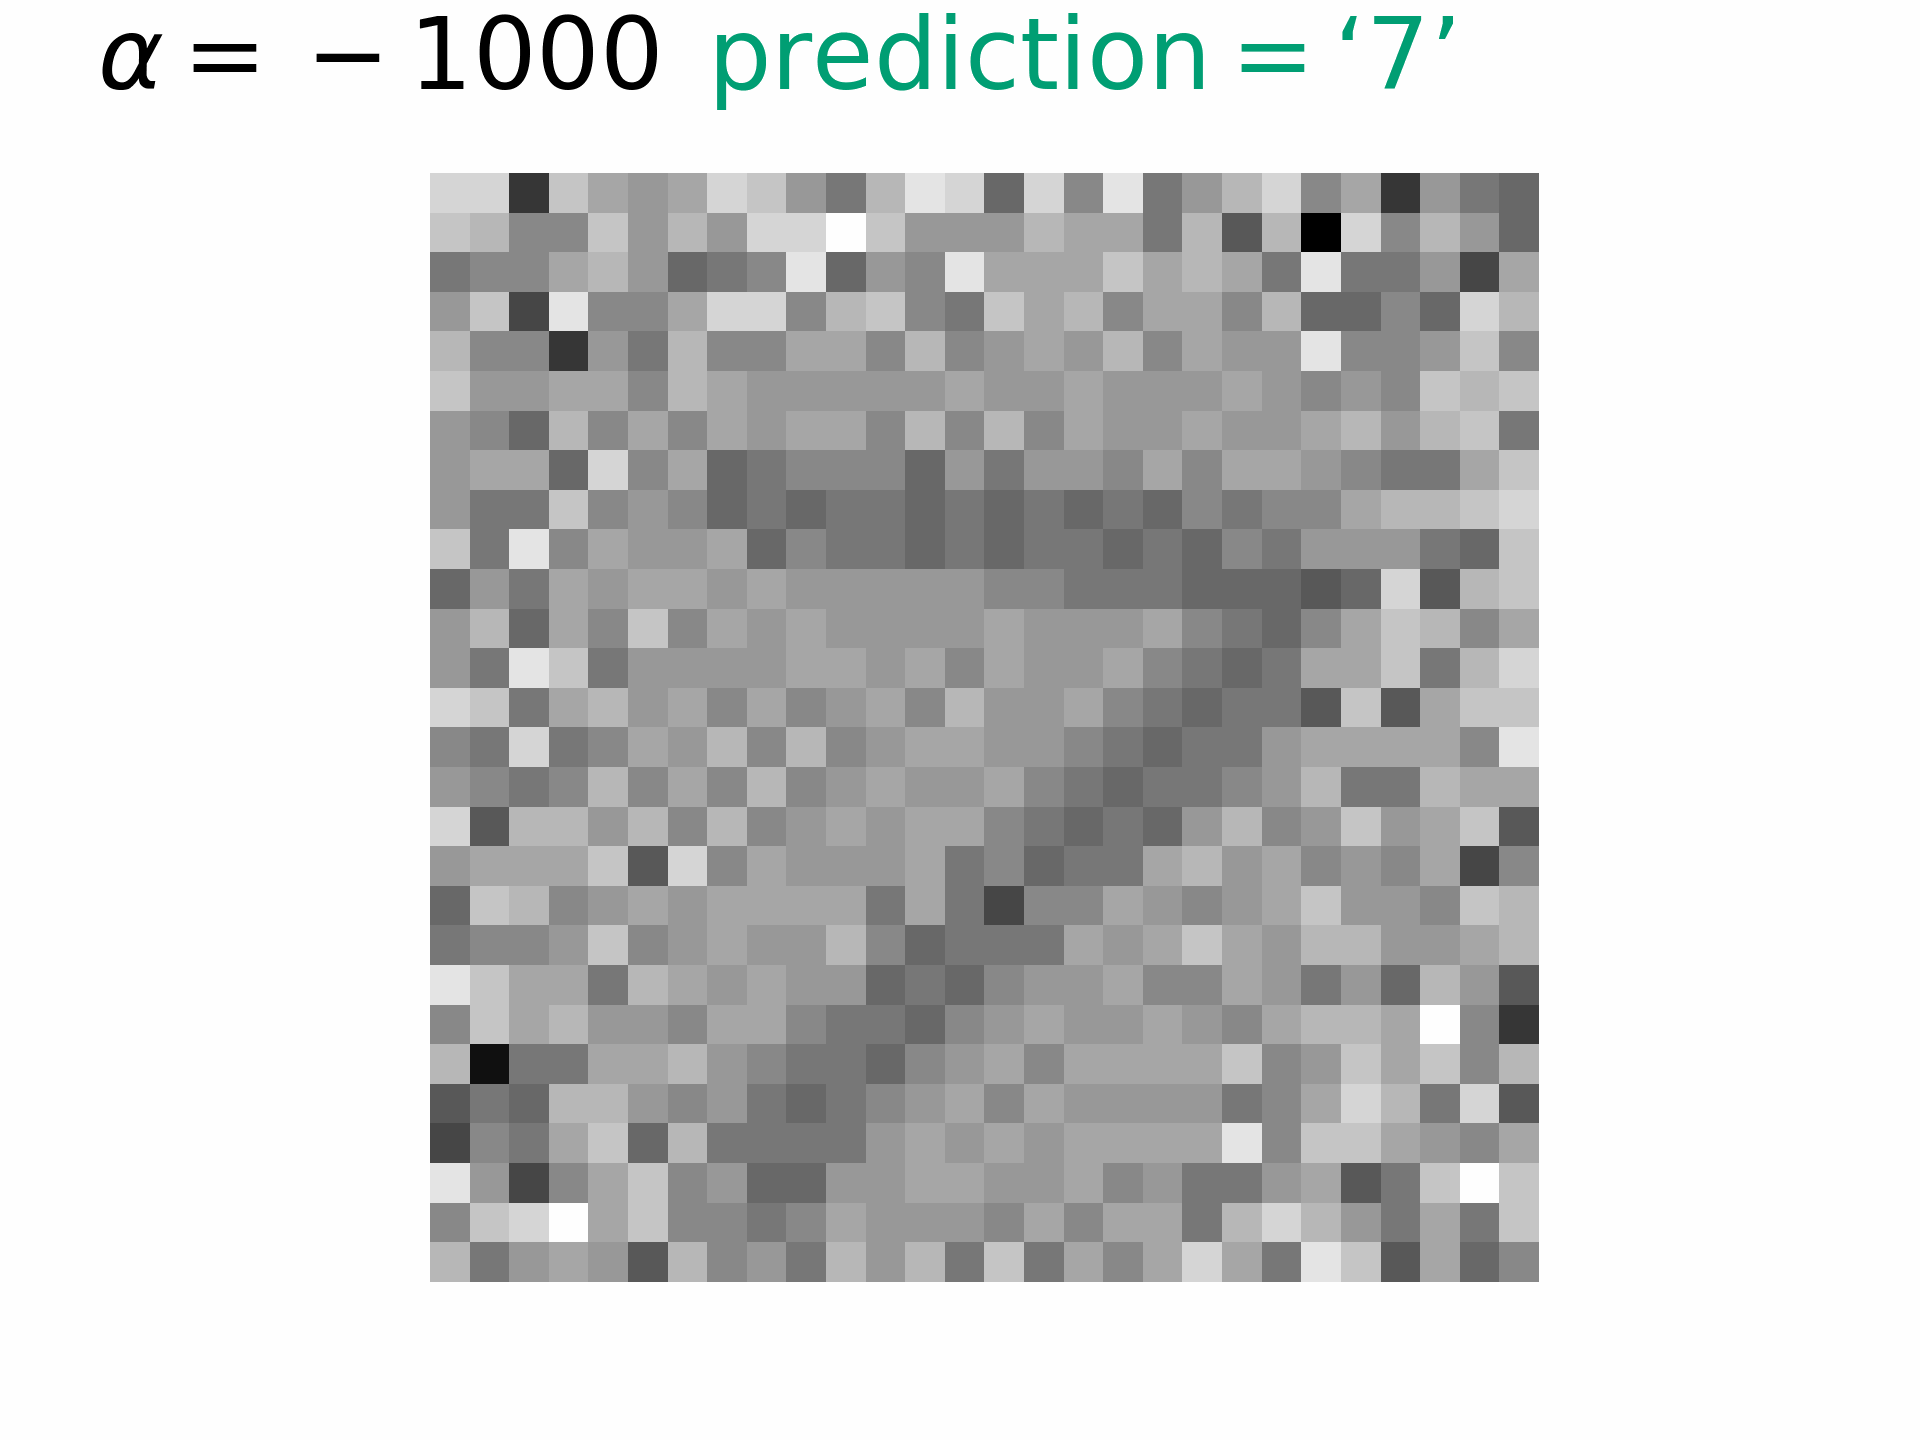
Setting to negative values means we are moving away from the hyperplane. That makes a ‘7’ look even more like a ‘7’ to the classifier. Does it to you?
Footnotes
-
I will consider only the base inputs that were classified correctly in the first place. ↩︎